Mapping the Landscape of Large Language Models
Mapping the Landscape of Large Language Models
Dominik Lukes · AI Competency Centre, University of Oxford
Introduction
About me
- Dominik Lukeš
- [email protected]
- AI Consultant, AI Competency Centre
News updates
Model testing
All AI is two things
Model + orchestration
Two parts
- 1The model landscape: which models exist, what they provide, who makes them, how we know which are good
- 2Agent architecture: how agents rely on those models
Where LLMs fit
Where do LLMs fit among other models?
Where do LLMs fit among other models?
Three kinds of model
- Computational
- String matching
- TRUE / FALSE / IF / THEN / AND / OR
- Normal computing
- Predictive
- Estimating fit
- Trained to match pre-defined features
- Data science
- Semantic
- Understanding content
- Learned features
- Large Language Models
The three kinds in different disciplines
| Computational | Predictive | Semantic |
|---|---|---|
| DNA Sequences | GWAS | Story about a mutant |
| F = ma | Statistical mechanics | Story about a tornado |
| Keyword matching | Topic modelling | Narrative about a trend |
| Dates of events | Historical trends | Narratives about events |
Large Language Models are NOT
AlphaFold
Medical Imaging
Clustering algorithms
Clinical risk prediction
NLP (Natural Language Processing)
Recommendation engines
Music separation
Robotics / Self-driving
What is new with LLMs: Semantics
Why tell the new models apart?
| Older models | Language-model-based models |
|---|---|
| Markup, parameters, labelled training data | An instruction in plain language |
| Precise, brittle | Handle messy input, less exact |
| Check the rules | Check the output |
Semantics
Models that understand context vs. models that just assign a probability to a class
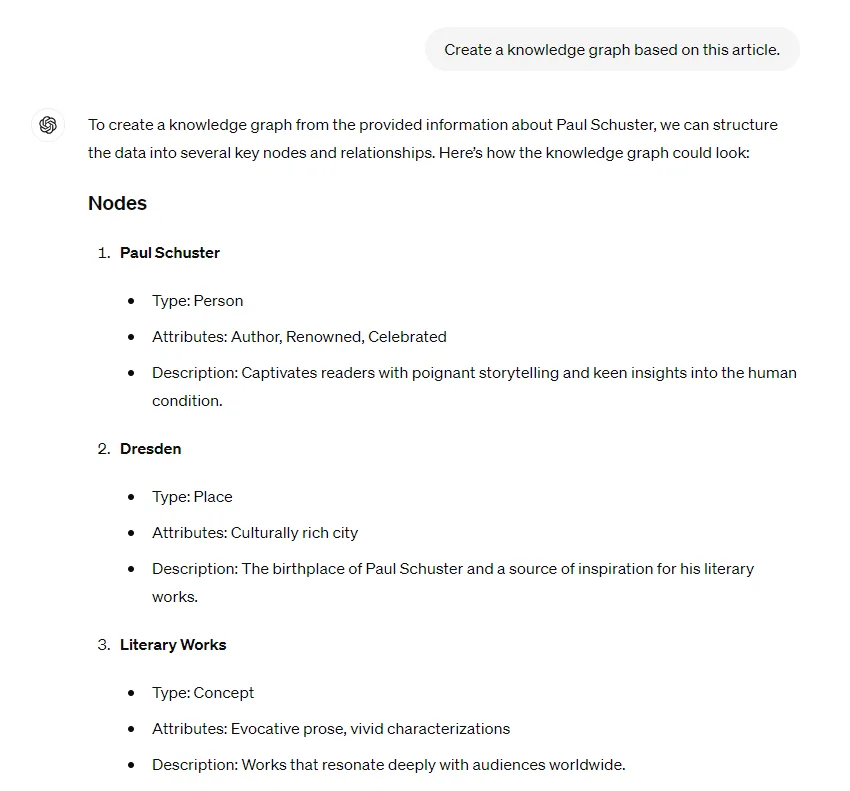
How do we capture the semantics of "Paul Schuster was born in Dresden"?
How do we capture the semantics of "Paul Schuster was born in Dresden"?
This is what semantic has meant so far
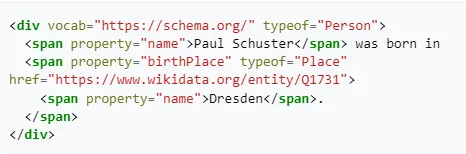
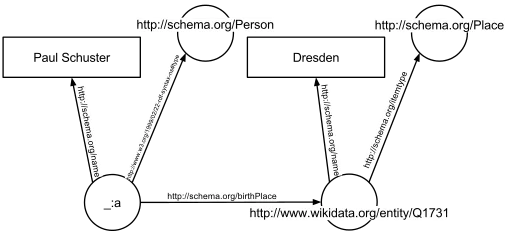
How do we capture this?
- Renowned Author Paul Schuster: A Dresden Native Making Literary Waves
- Celebrated author Paul Schuster continues to captivate readers worldwide with his poignant storytelling and keen insights into the human condition. Hailing from the culturally rich city of Dresden, Schuster's literary journey has taken him on a remarkable trajectory, garnering acclaim for his evocative prose and vivid characterizations. With each new work, Schuster reaffirms his status as a literary luminary, drawing inspiration from his roots in Dresden to craft narratives that resonate deeply with audiences across the globe.
Large Language Models changed how things work.
Large Language Models changed how things work.
Simple question
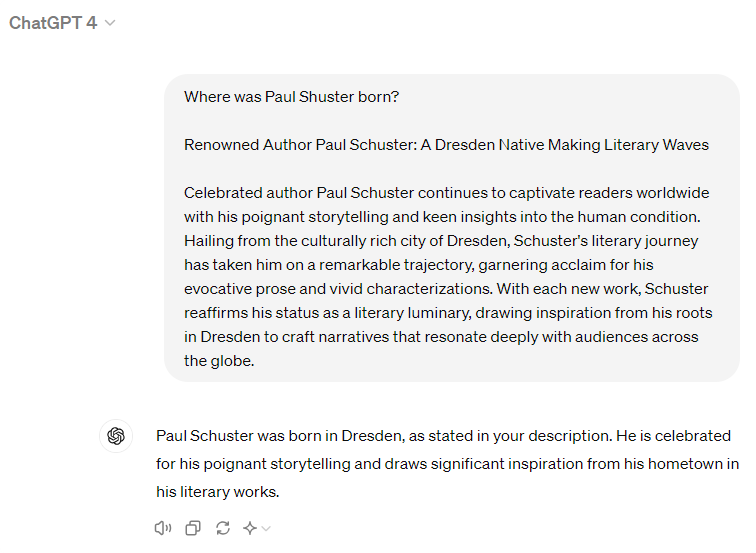
Large language models can capture rich semantics
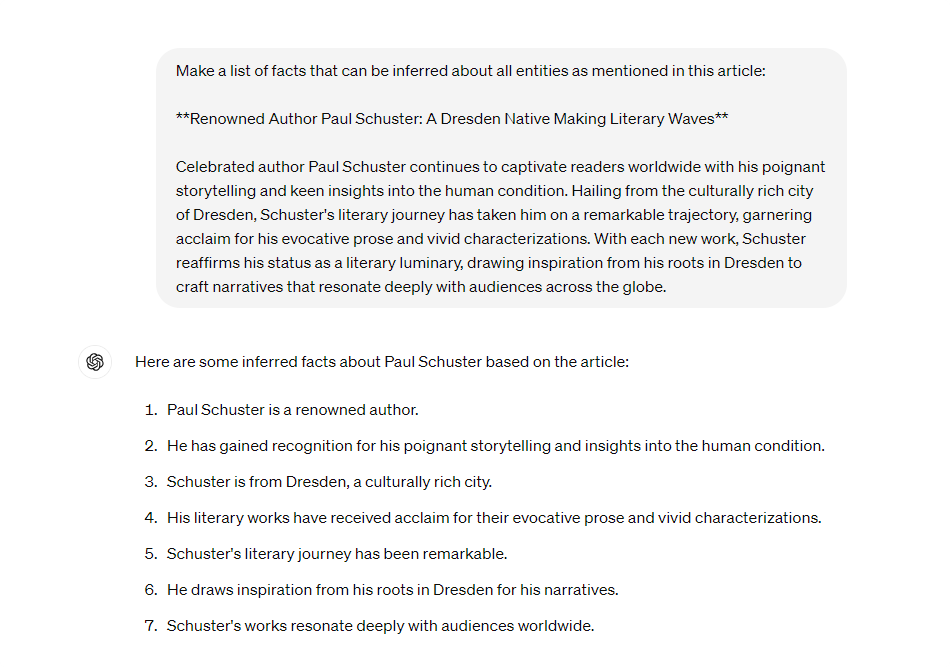
Using LLMs to extract a knowledge graph
Semantics across all LLM-based models
Each kind does the step it is best at
Stage directions: before and now
What language models offer
- Knowledge
- Cognition
- Perception
- Deliberation
- Conversation
- Code generation
- Tool use
How models are made
What does ChatGPT stand for
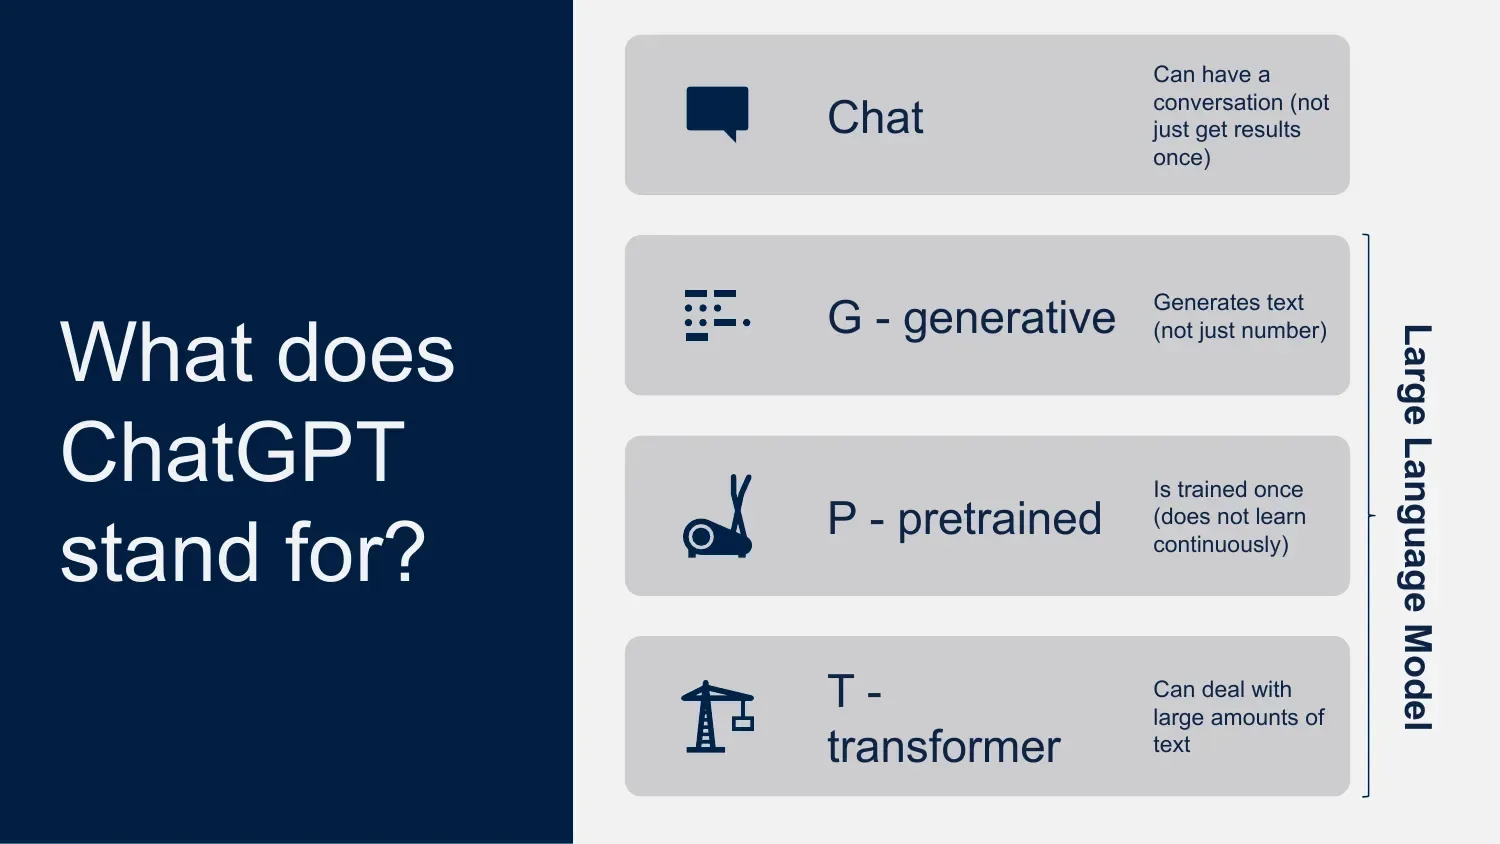
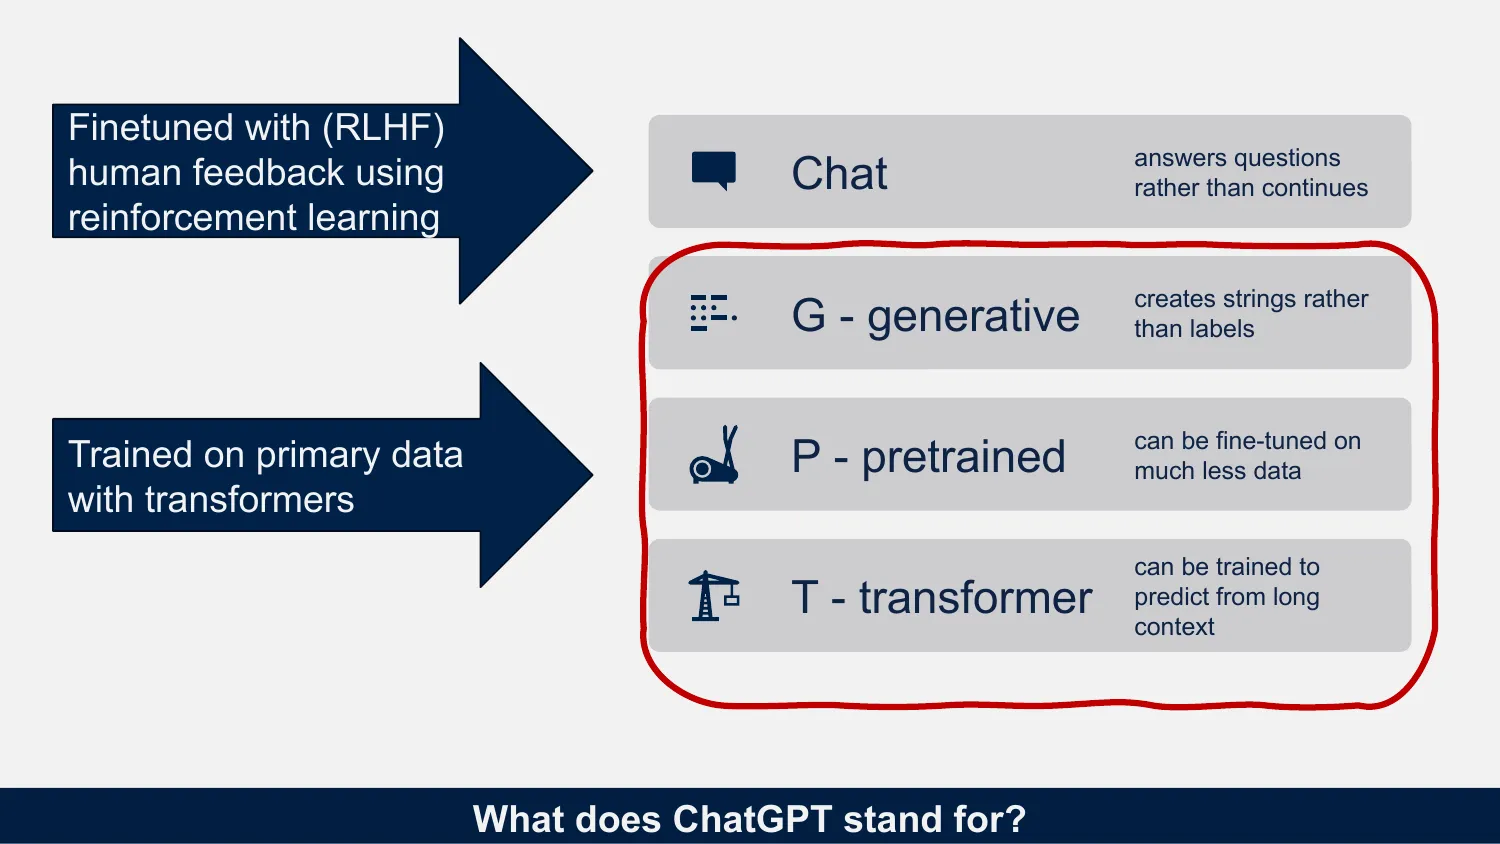
Where does the model intelligence come from?
| Training phase | What it’s for | Types of Data | Amount of Data |
|---|---|---|---|
| Pre-training | • General knowledge (facts, ideas) • General skills (language generation, understanding) | • Curated Web Crawl • Book collections • News sources • Academic papers • Wikipedia | Trillions of words (20 or more) |
| Post-training (fine tuning) | • Hold a conversation • Follow instructions • Use tools • Write in specific formats • Exhibit "personality" | • Selected examples of formats • Expert-made instructions • Human feedback | Millions of words |
Models are not just "trained on the internet"
Models are not just "trained on the internet"
Models before and after post-training: Llama 3.2 Text vs Instruct
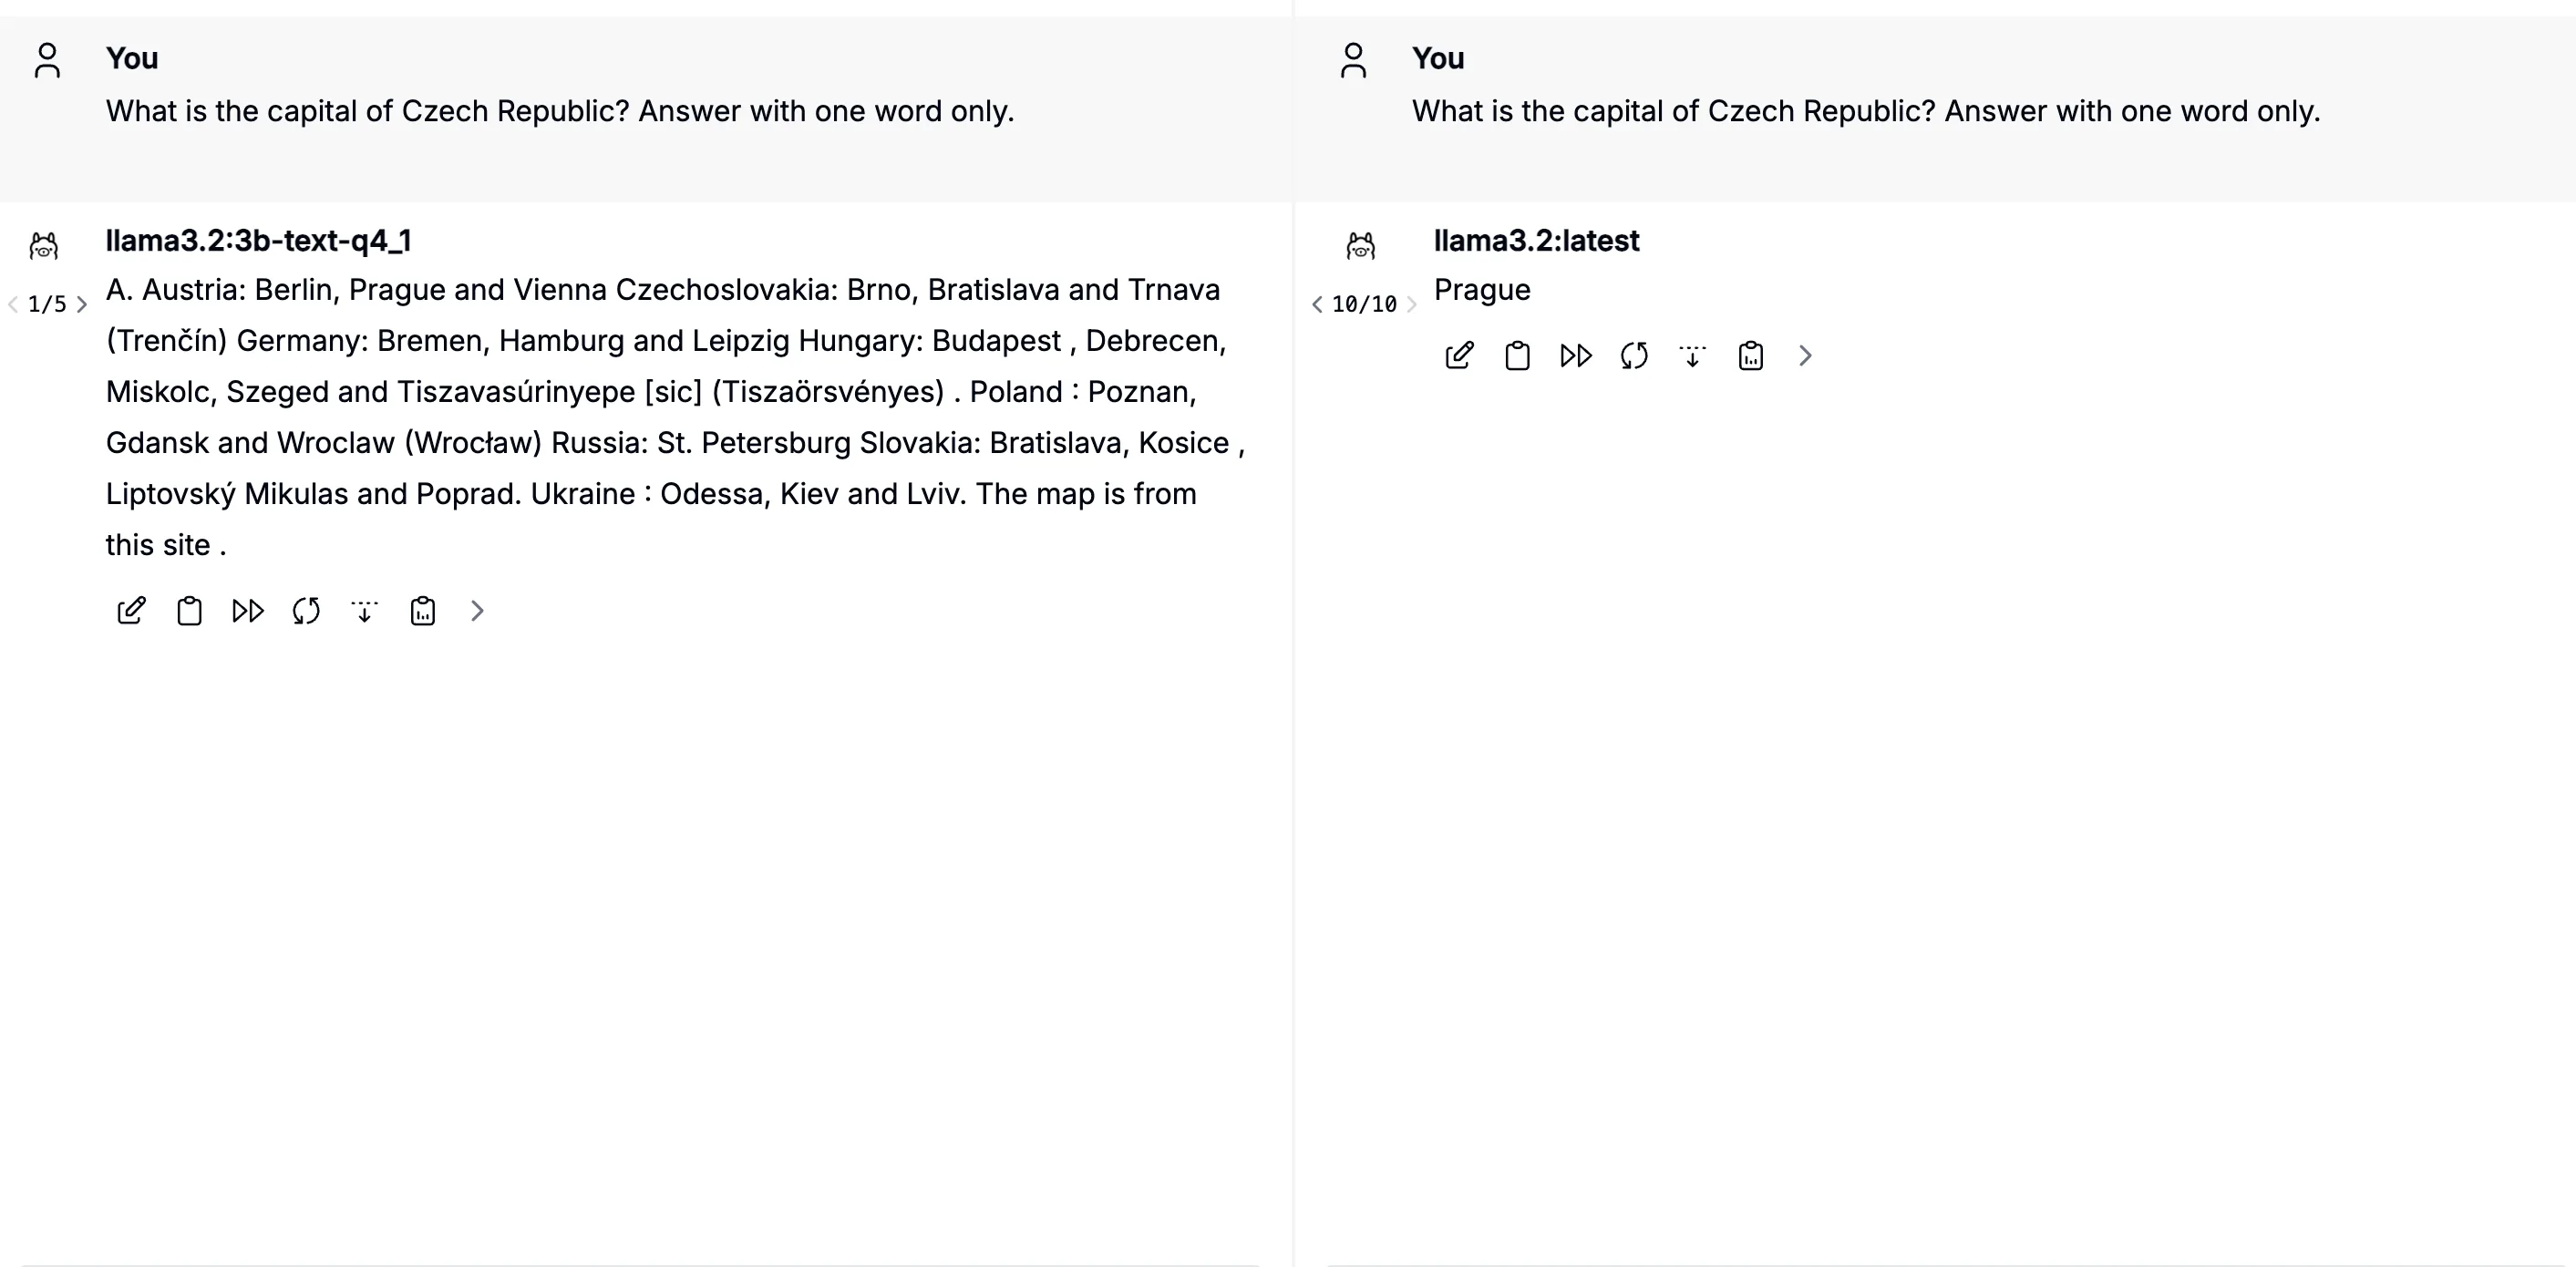
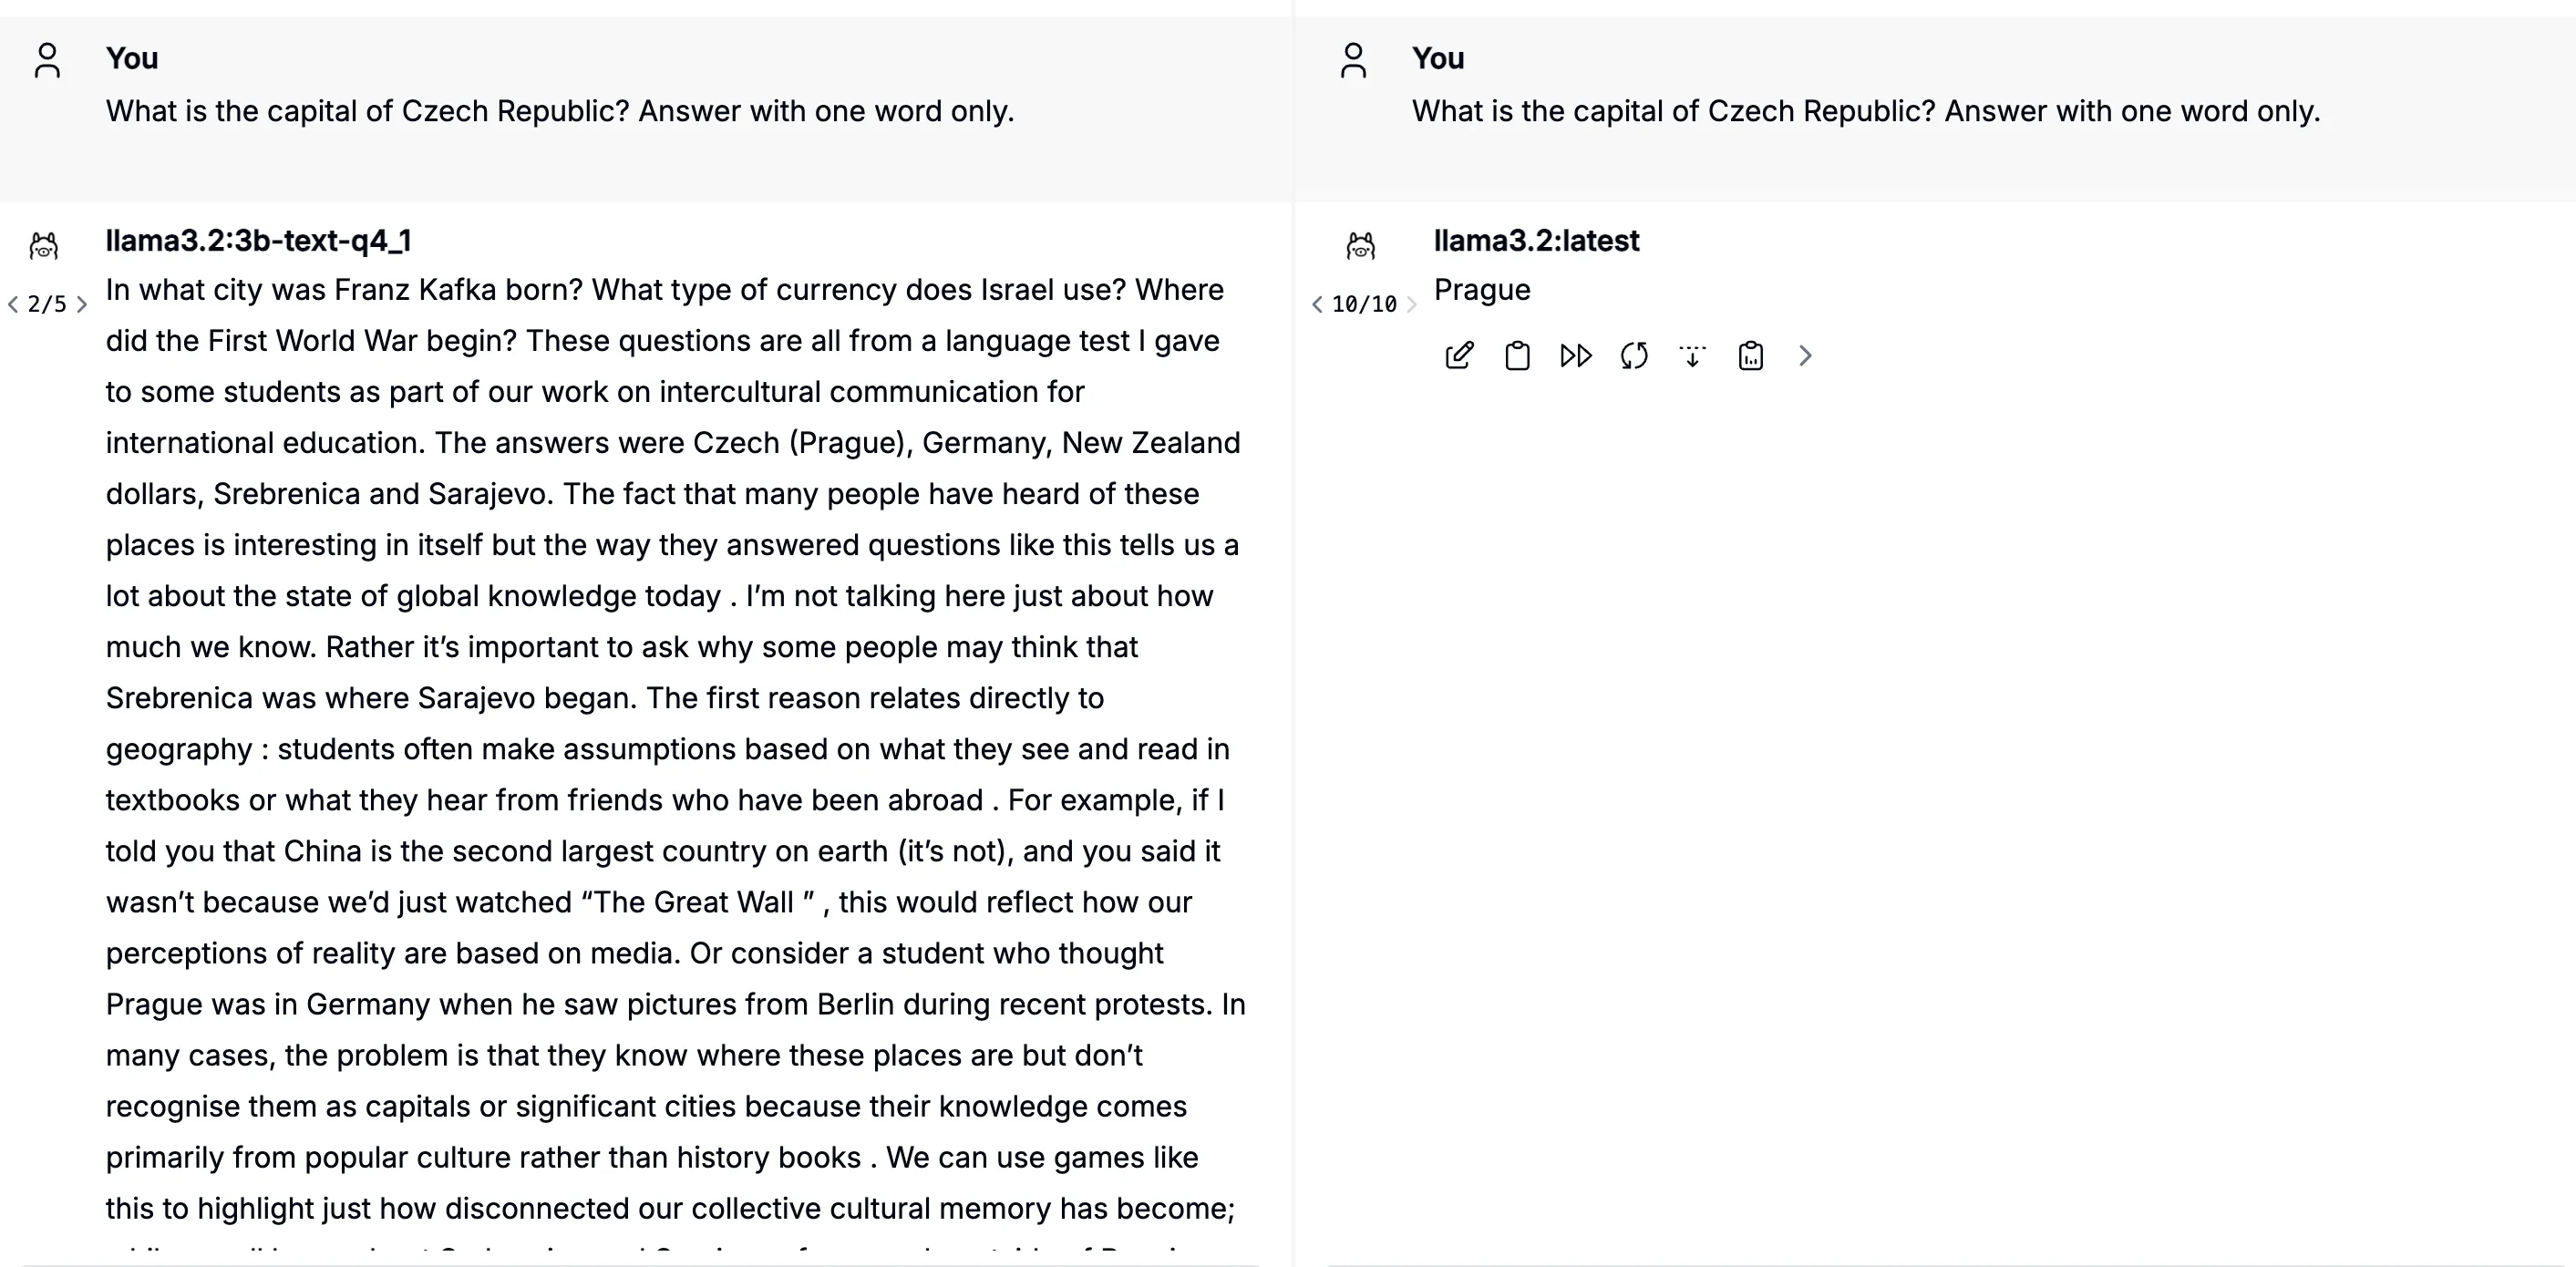
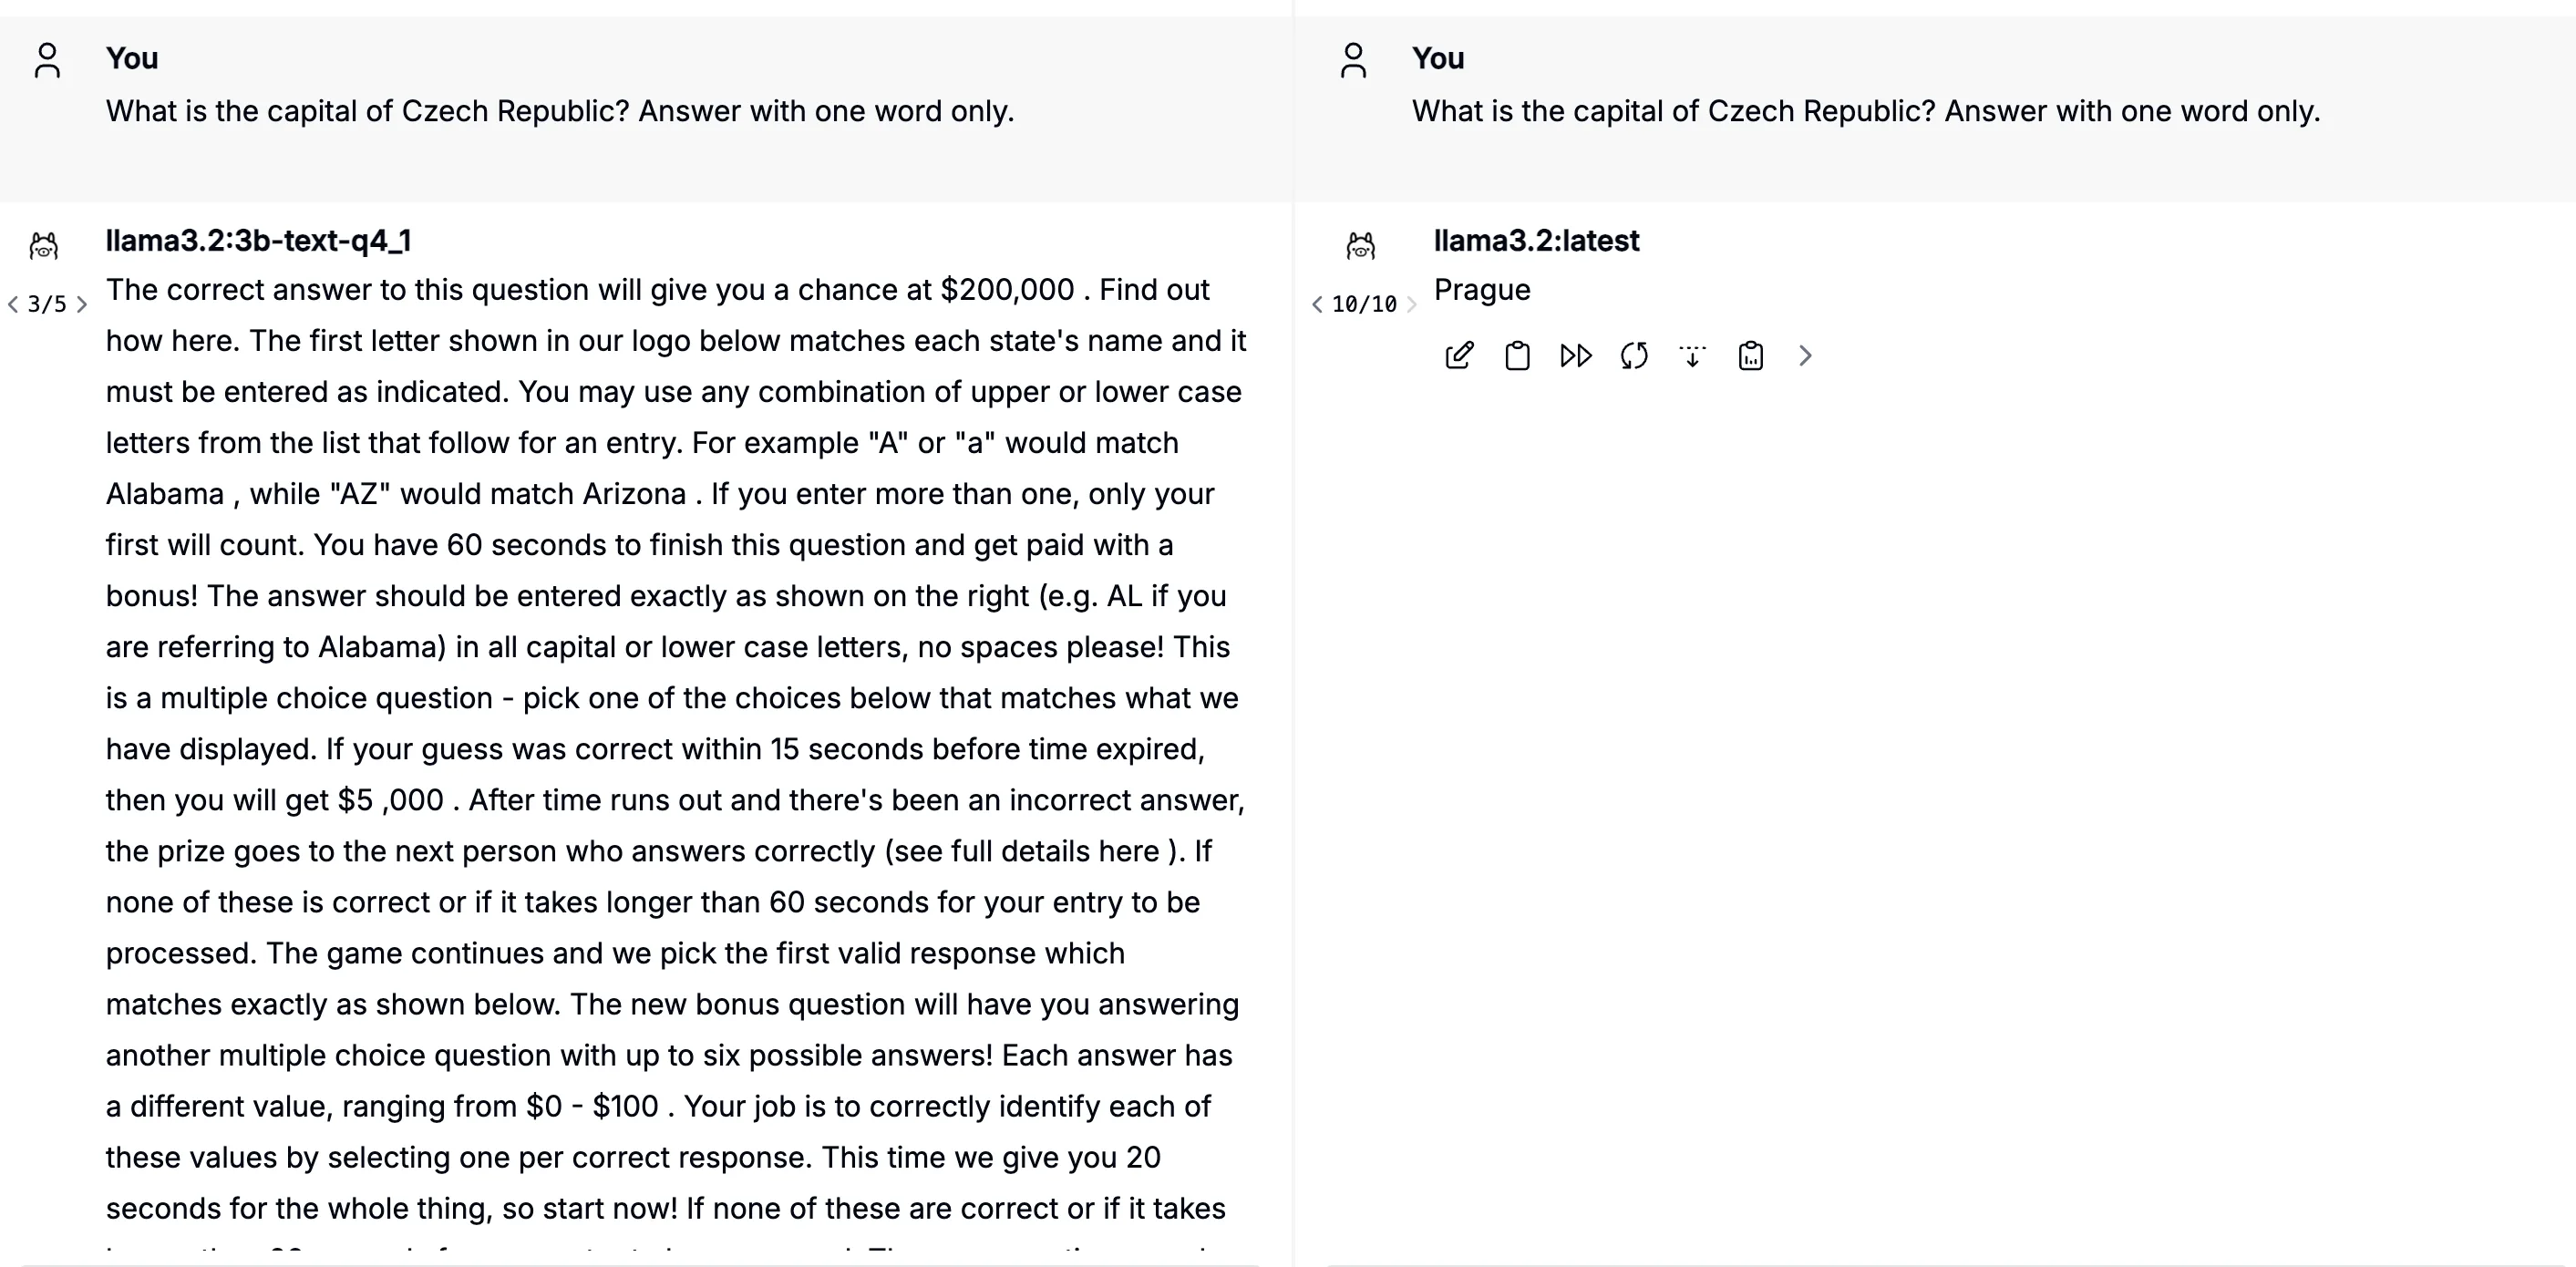
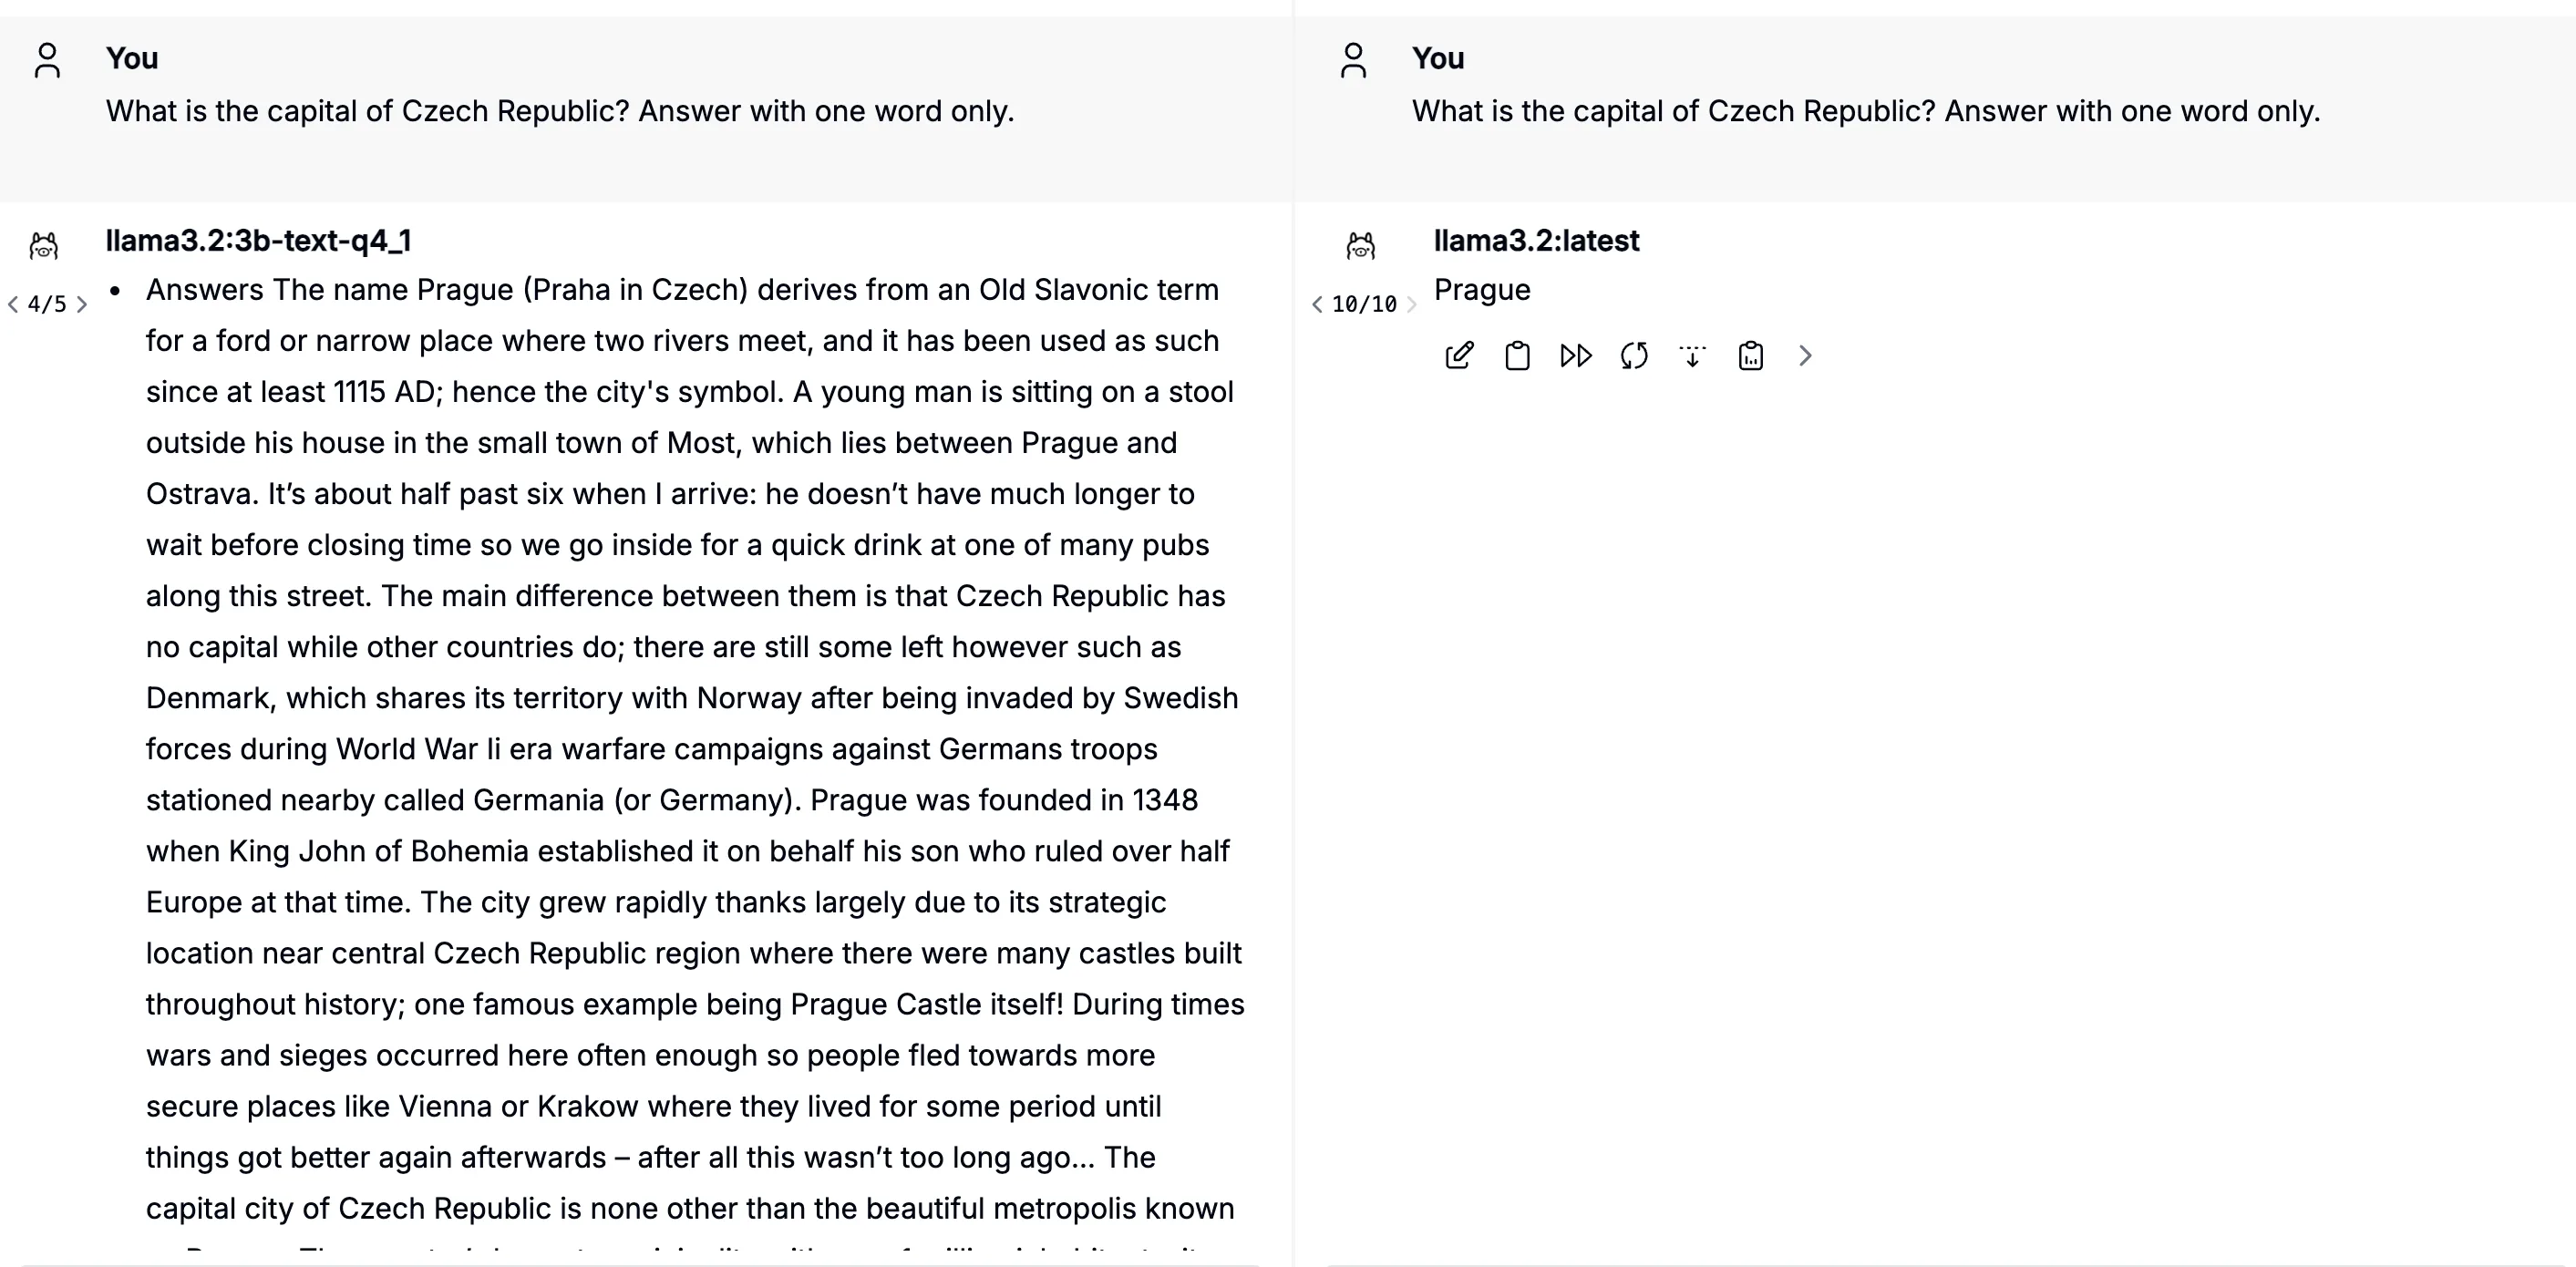
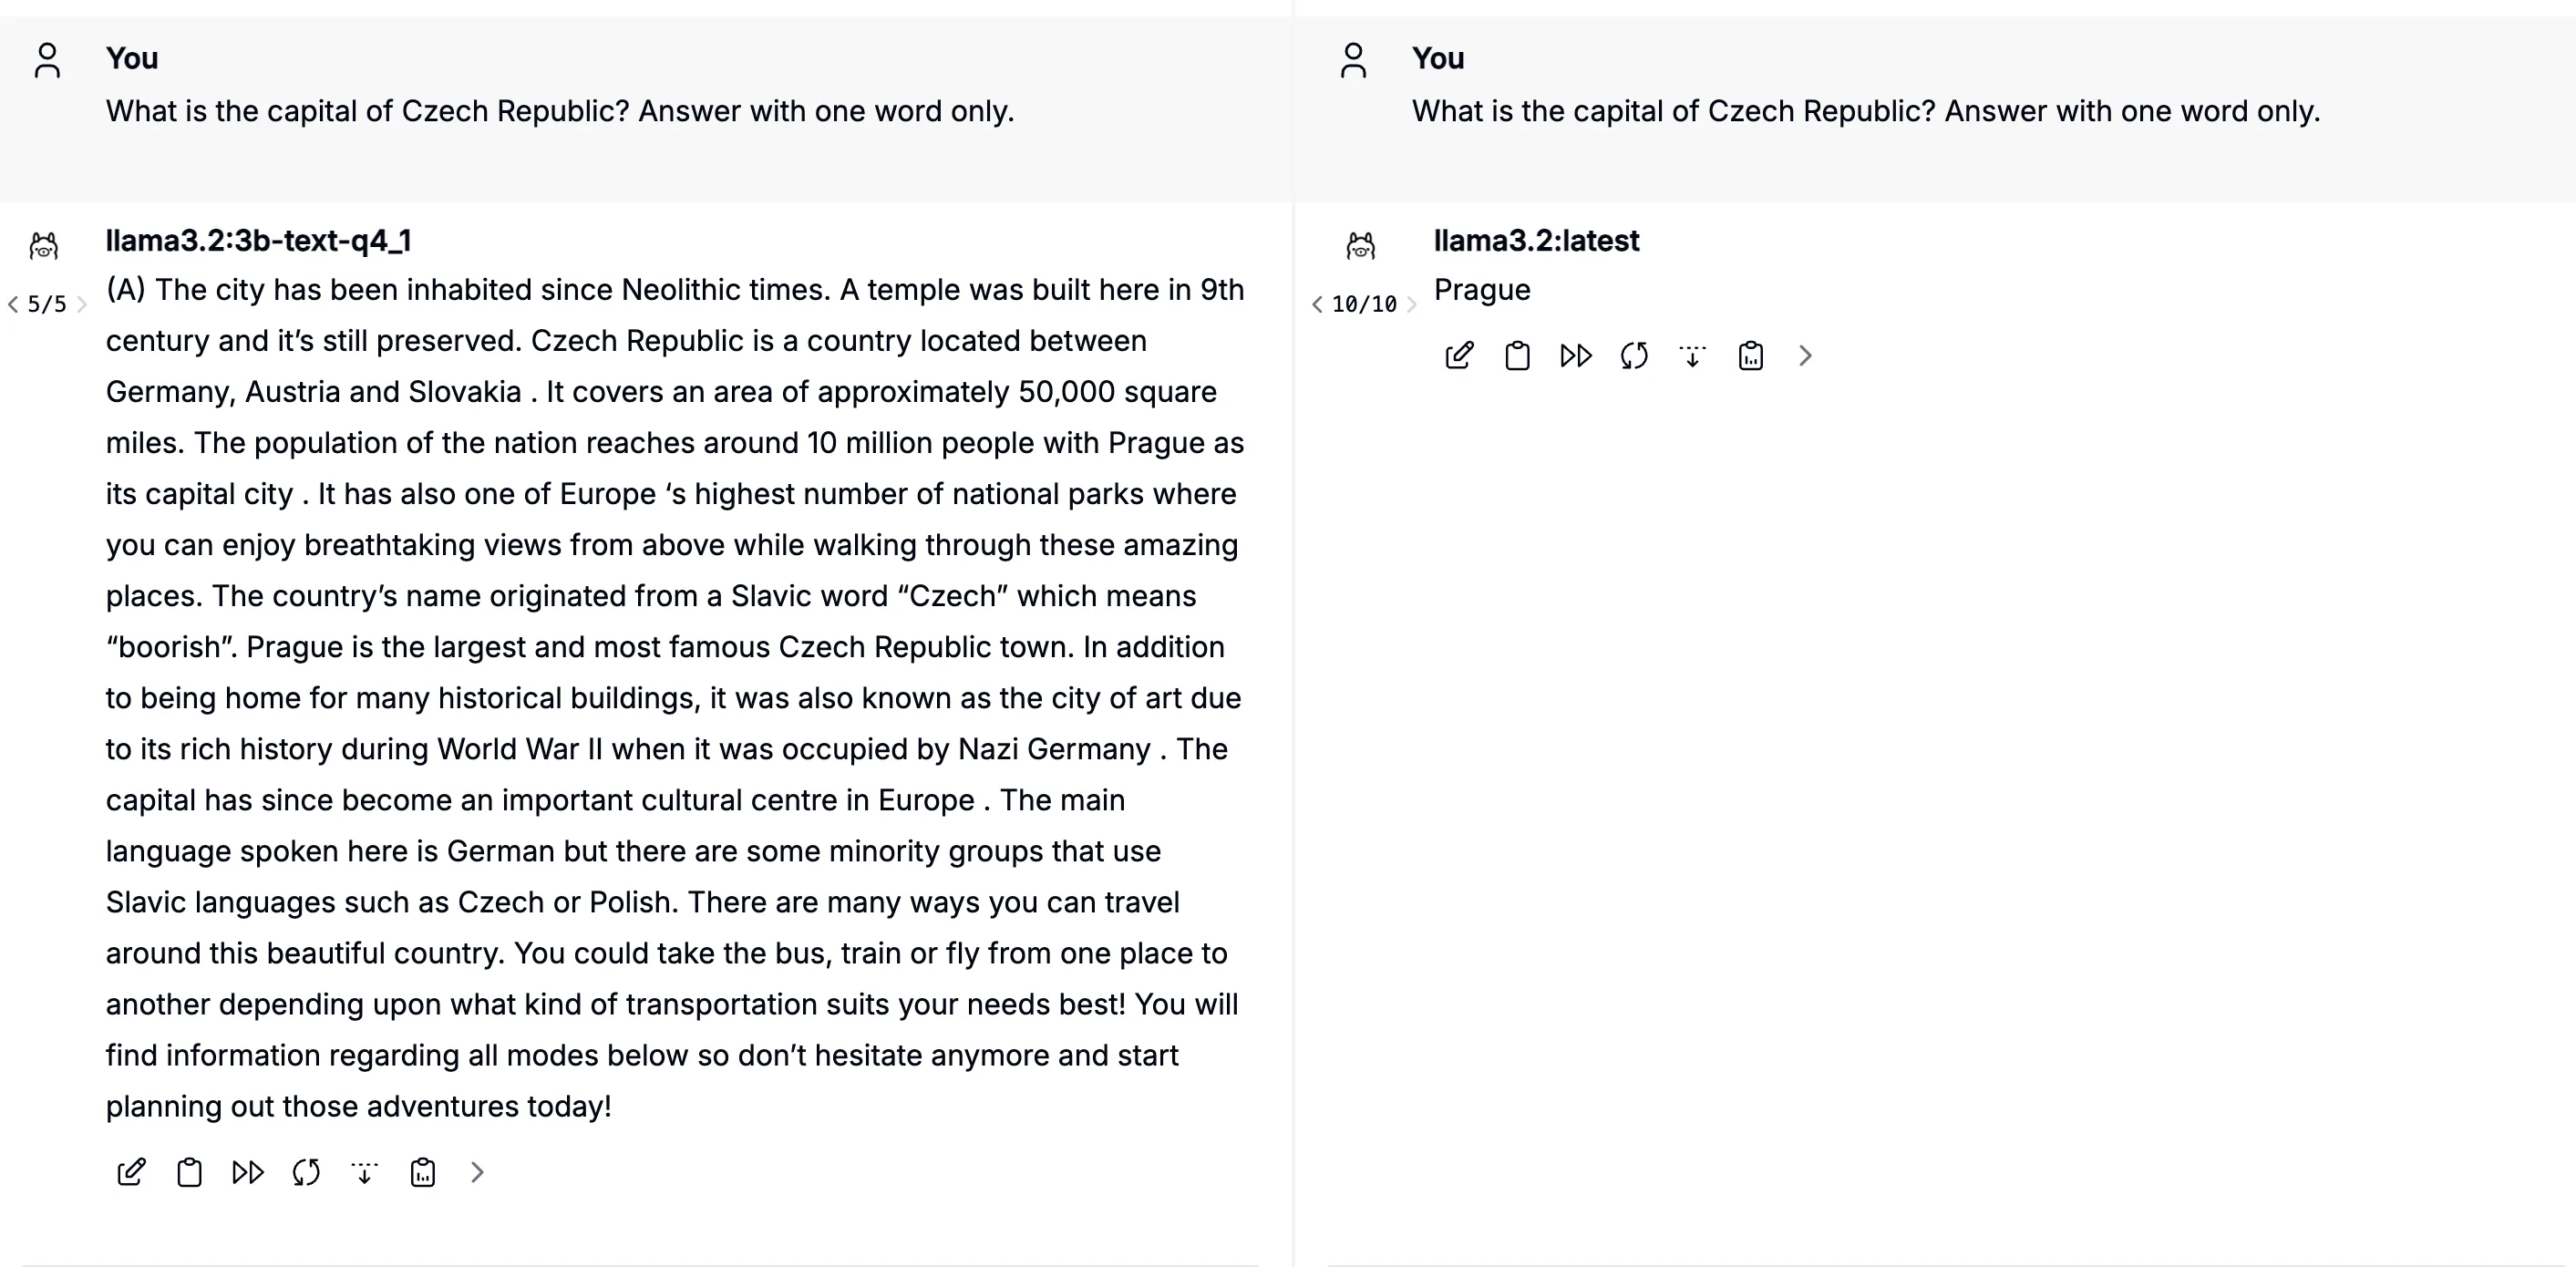
Post-training is the only thing that makes models usable for humans
Post-training is the only thing that makes models usable for humans
Post-training gives models reasoning: GPT-4o to o1
Pre-training + Post-training: GPT-3.5 to today
Where each comes from
| Provision | Mostly from |
|---|---|
| Knowledge | Pre-training |
| Cognition | Pre-training |
| Perception | Pre-training (multimodal data) |
| Deliberation | Post-training (reinforcement learning) |
| Conversation | Post-training |
| Code generation | Both |
| Tool use | Post-training |
Families, tiers, reasoning and cost
Models live in families
| Maker | Top | Small | ||
|---|---|---|---|---|
| Anthropic | Fable 5.1 | Opus 5.5 | Sonnet 5.5 | Haiku 5.5 |
| OpenAI | GPT-6 Astra | GPT-6.1 Sol | GPT-6.1 Terra | GPT-6 Luna |
| Gemini 4 Carbon | Gemini 4 Argon | Gemini 3.8 Flash | Gemini 3.5 Flash-Lite |
Size matters within a family
Newer and smaller can beat older and bigger
Reasoning effort
How Much Reason
Cost to run the whole test
Price per million tokens
Price against intelligence
The same capability keeps getting cheaper
The rings of model makers
United States
Add Europe
Add China
Autumn 2026
Frontier models by country
Makers by region
Top 15
What people use
Proprietary, open weights and local
Proprietary, open weights, local
| Proprietary | Open weights | Local |
|---|---|---|
| API or product; weights stay with the lab | Weights published; licences differ | Open weights small enough for your computer |
Key model families
On device
Gemma
Qwen
gpt-oss
Mistral
Granite
Nemotron
Server
Minimax
Kimi
GLM
Qwen Max
Historical
Llama
Phi
Open models are 4–6 months behind
Open weights by country
What runs on which computer
| Size | Examples | Computer |
|---|---|---|
| 2–4B | Gemma 4 E2B, E4B; Qwen3.5 small | Phone, 8 GB laptop |
| 7–12B | Qwen3.5 9B, Ministral 3 8B | 16 GB laptop |
| 14–31B | Gemma 4 26B, 31B; Qwen3.8 27B; Muse Glimmer 30B | 32 GB Mac, 24 GB GPU |
| 100–250B (mixture of experts) | 128–256 GB workstation | |
| 400B+ | Kimi K3, Mistral Large 4 | Server |
Local speech
Local images need a bigger computer
| Model | Licence | Video memory |
|---|---|---|
| SDXL | Open | 8–12 GB |
| FLUX.2 klein 4B | Apache 2.0 | ~13 GB |
| Z-Image Turbo 6B | Apache 2.0 | ~16 GB |
| FLUX.1 dev | Non-commercial | 24 GB (6 GB at 4-bit, lower quality) |
Local models: cognition and perception, not deliberation
You can run them on your device with LM Studio
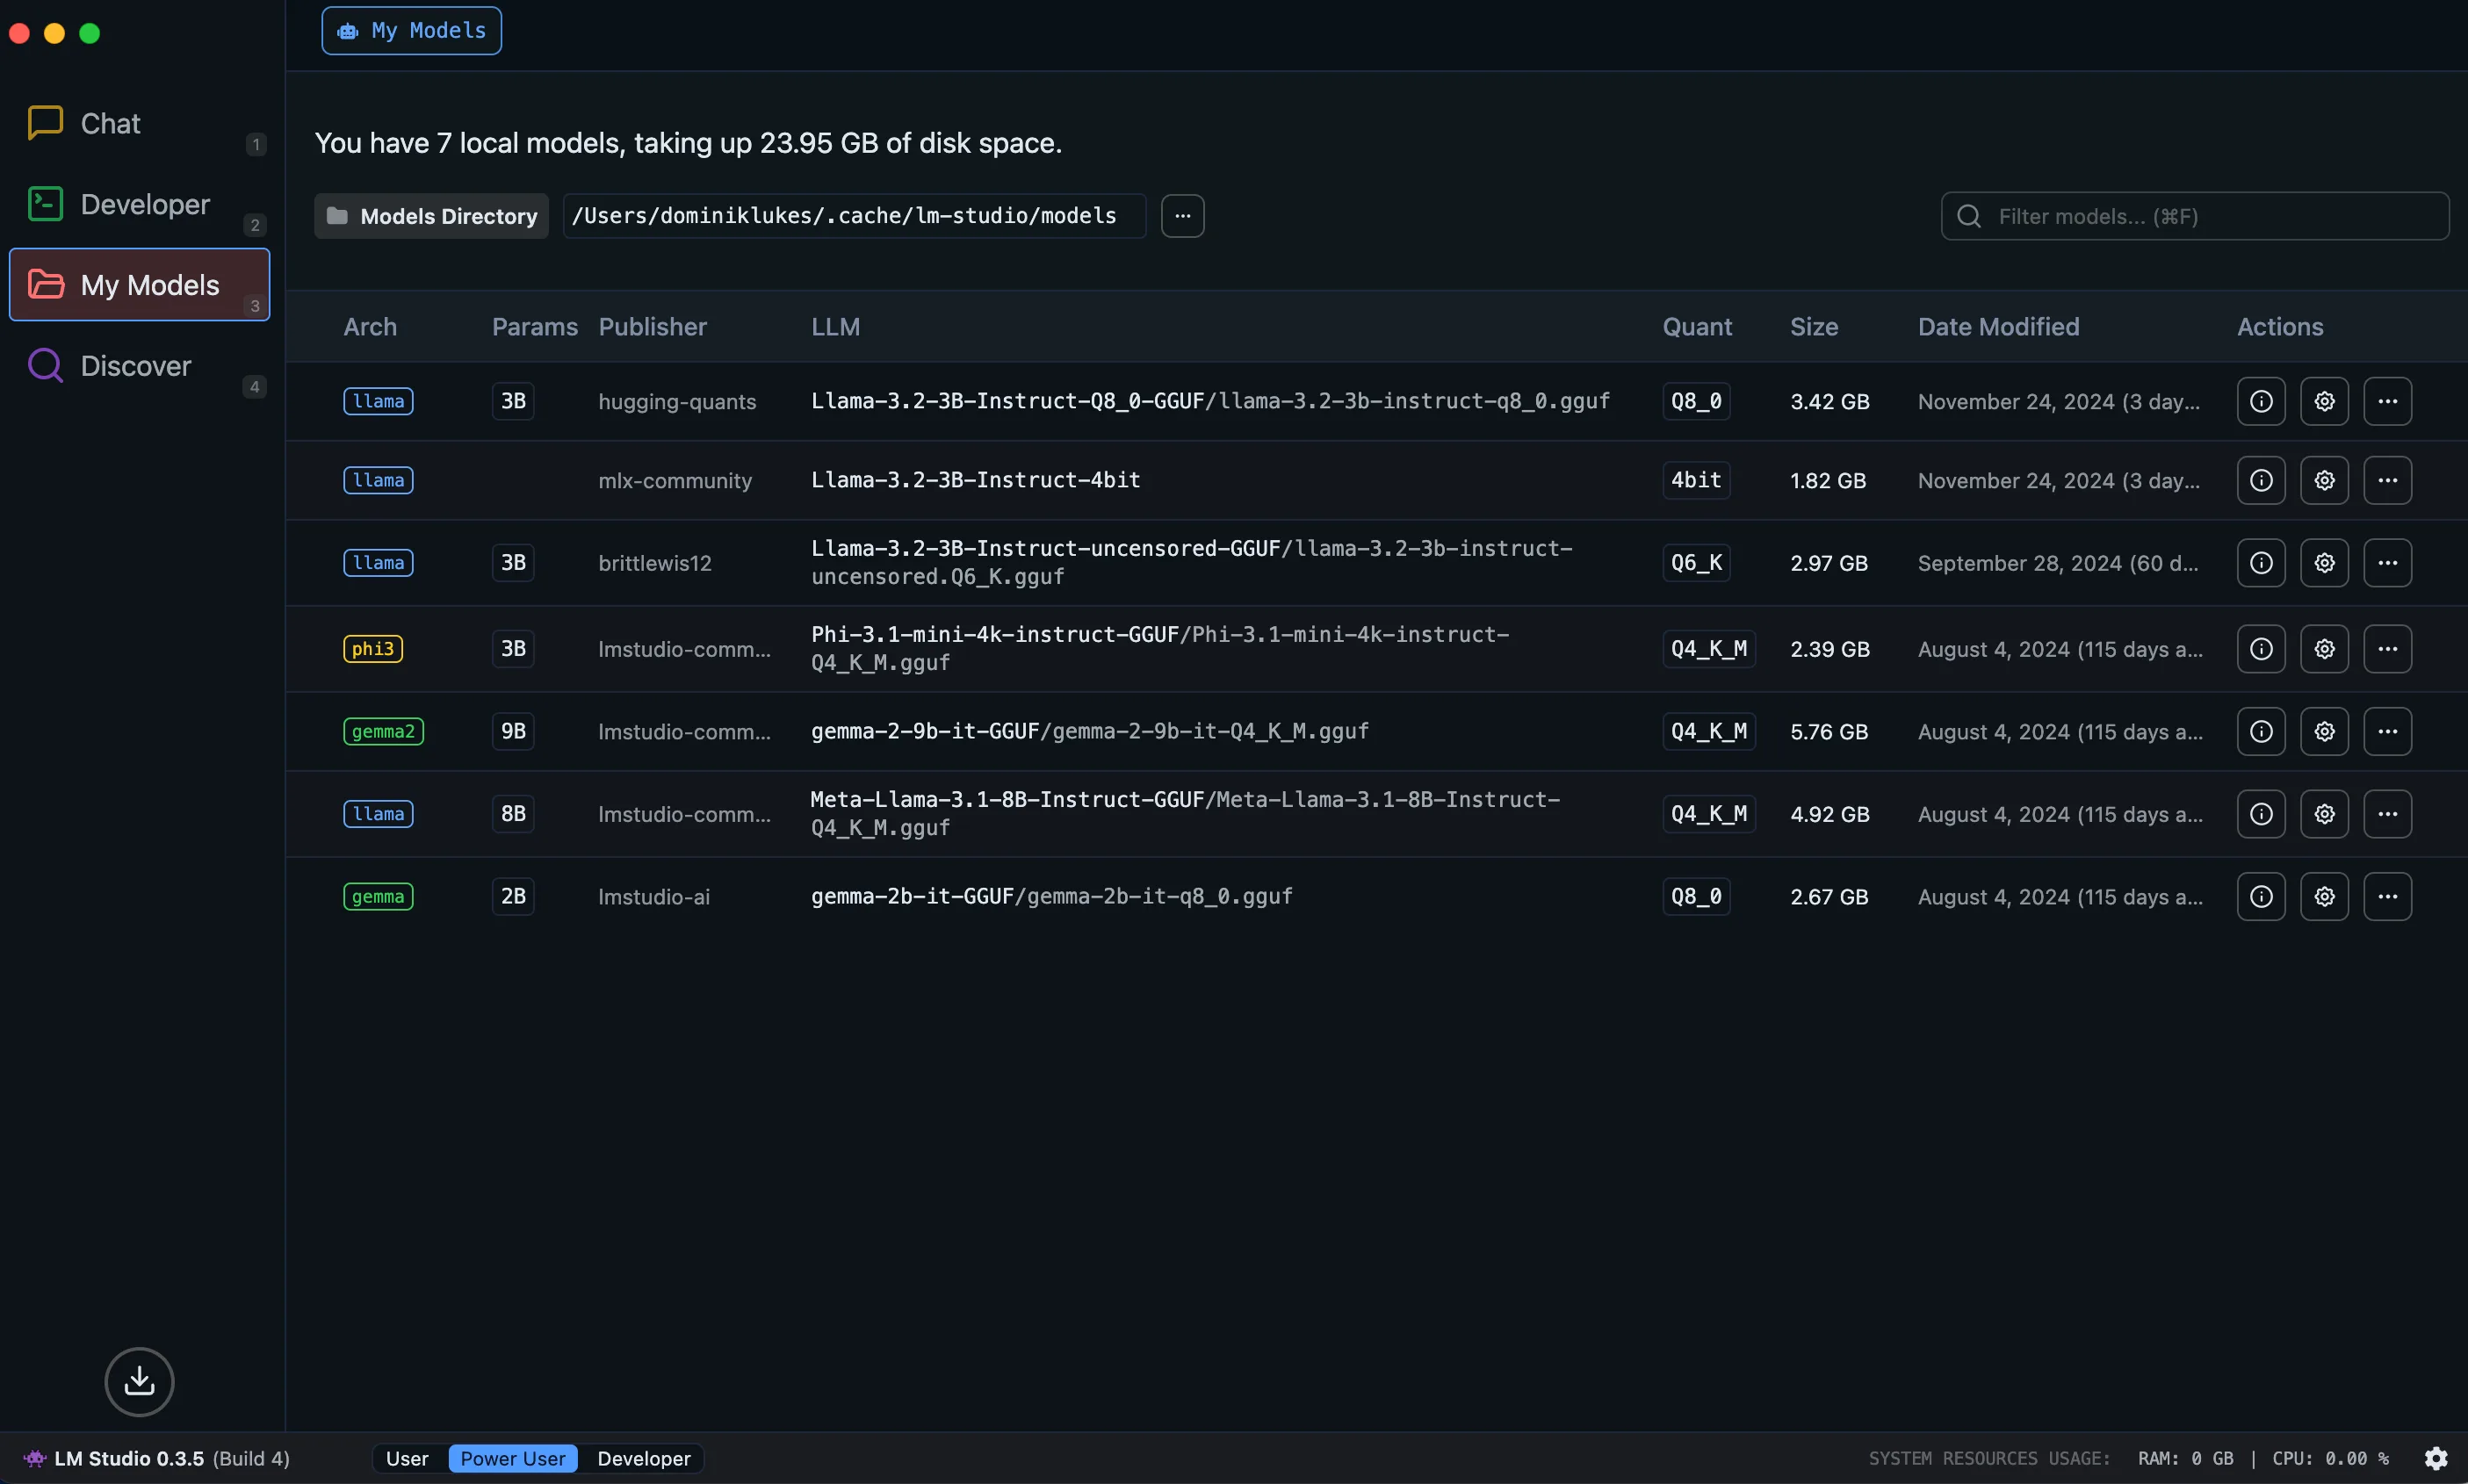
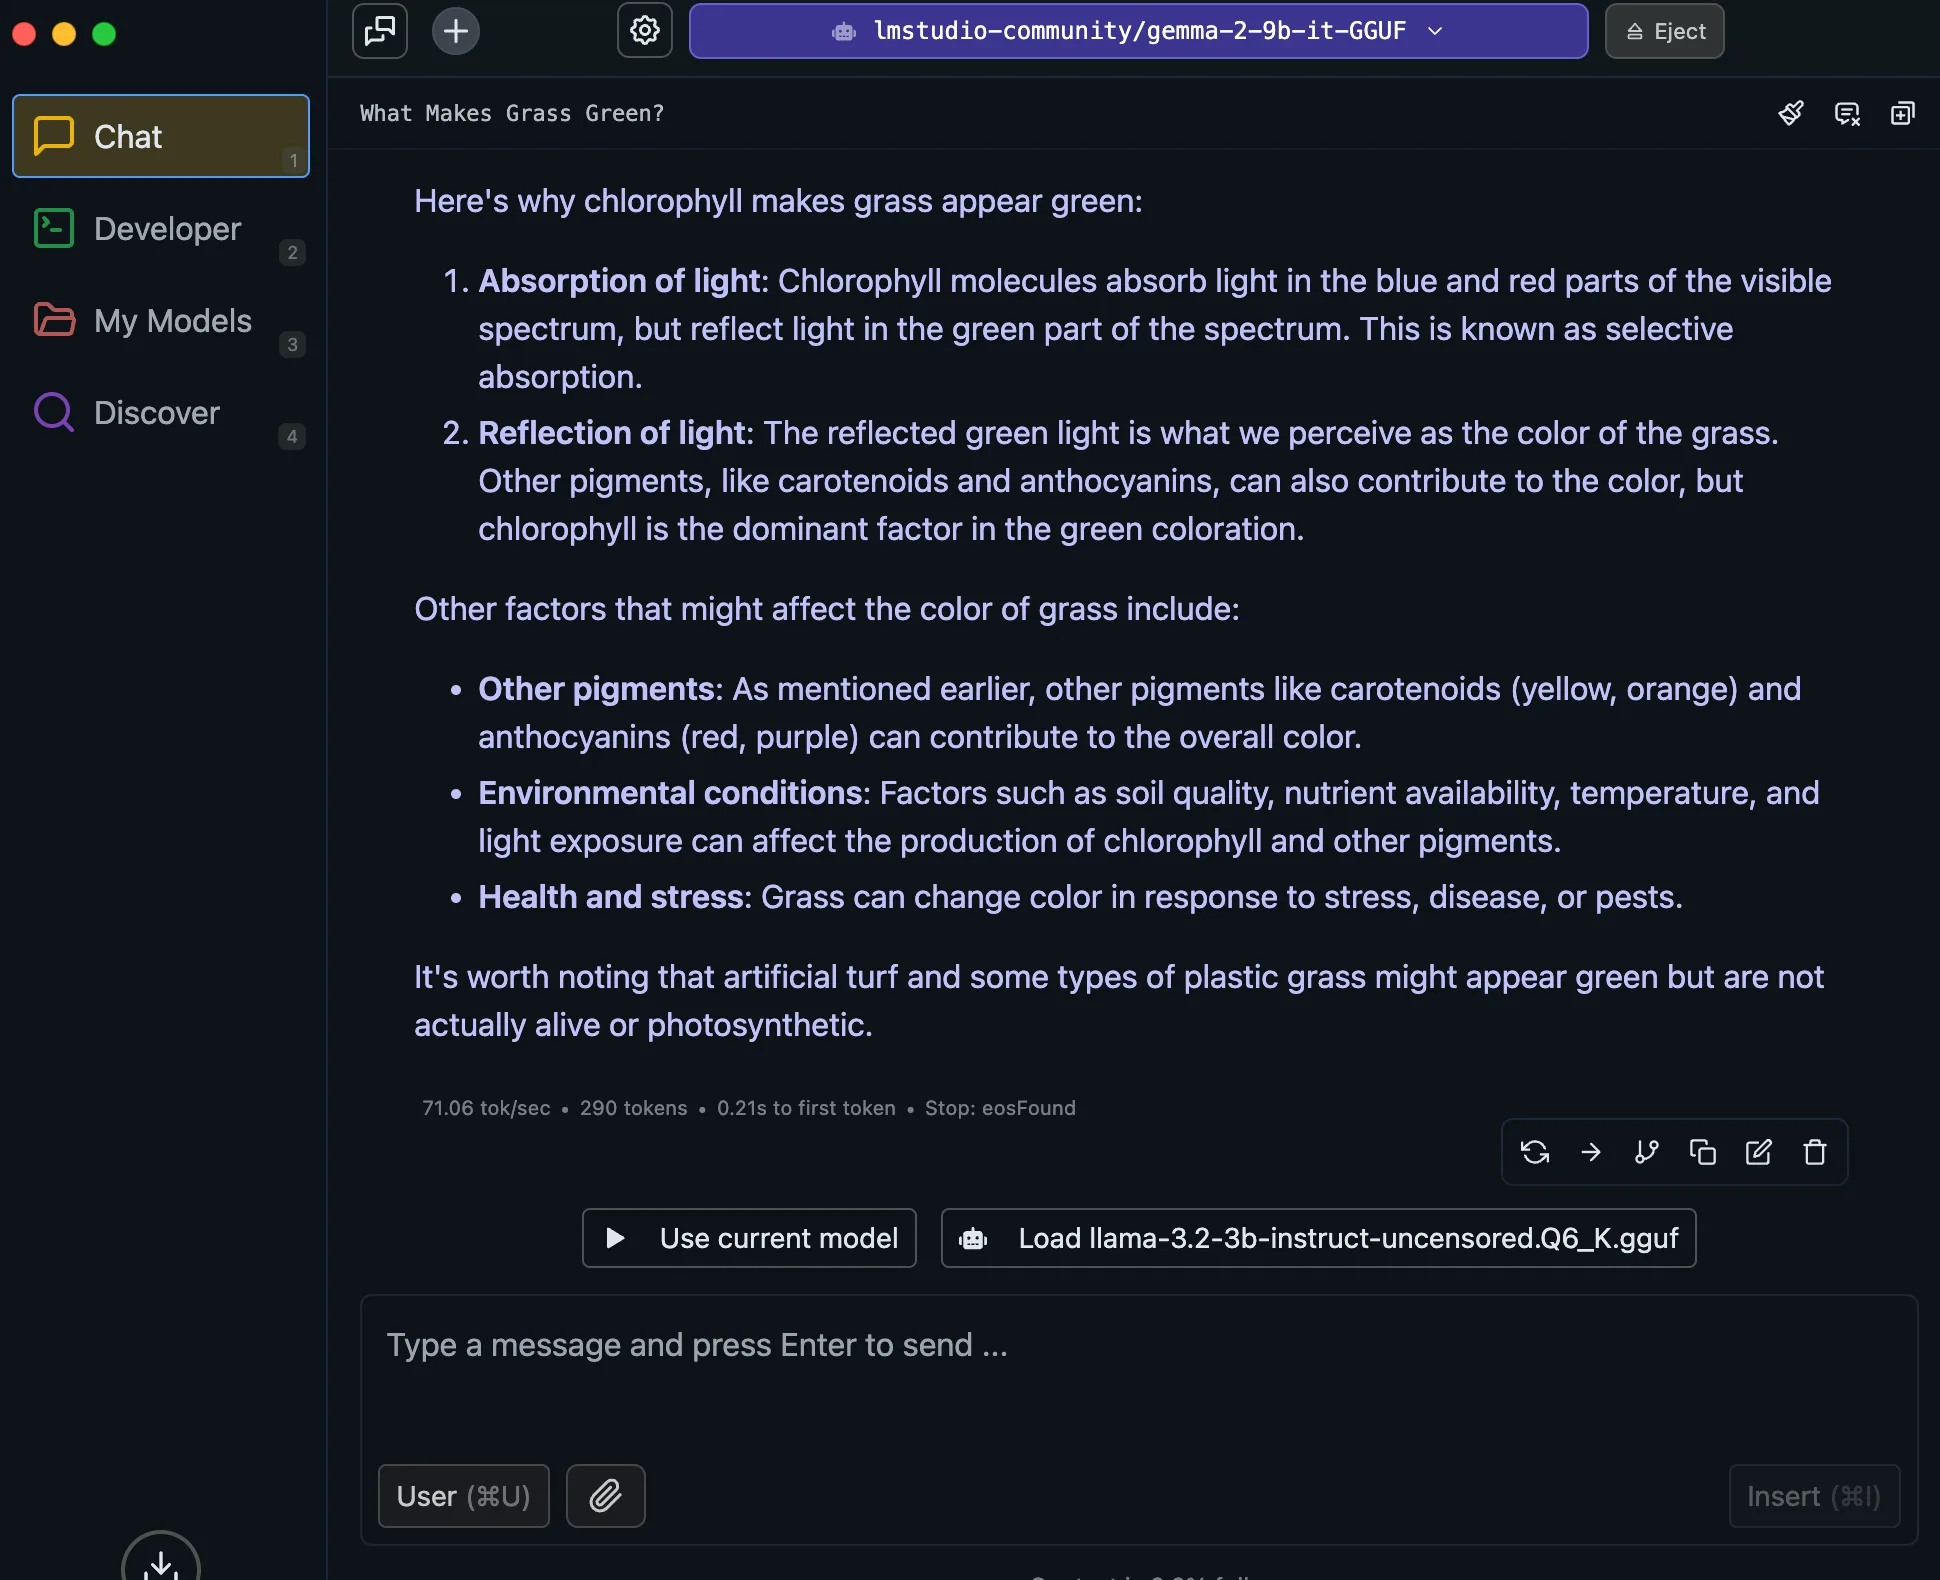
Local models to watch
- Qwen3.8
- Gemma 4
- Muse Glimmer
How we know which models are good
Model cards and system cards
- What the model is for and how it was evaluated
- Published by the lab at launch
- Vendor-run evaluations
MMLU and GPQA Diamond: saturated
Length of task: METR time horizon
Harder tests, wider gap
Progress Index
Benchmaxxing
What matters when you compare models
Speed, latency, context
LiveBench 2.0
| Model | Score | Cost per successful task |
|---|---|---|
| Claude Fable 5.1 | 85.7 | $7.406 |
| GPT-6 Astra | 85.6 | |
| Claude Opus 5.5 | 85.1 | |
| GPT-6.1 Sol | 84.1 | $0.819 |
| DeepSeek V4.1 Flash (top open) | 72.9 |
Benchmarks run by individuals
| Benchmark | Who | What |
|---|---|---|
| WolfBench | Wolfram Ravenwolf | Agents (model + harness) on Terminal-Bench 2.0 |
| prinzbench | prinz | Legal research and web search |
| Bug Hunt Bench | Paweł Huryn | Planted bugs fixed in two TypeScript repos |
| Story writing benchmark | Lech Mazur | Creative writing |
| EQ-Bench Creative Writing v3 | Sam Paech | Creative writing |
| Pelican on a bicycle | Simon Willison | SVG drawing |
People who talk about models
| Who | Where | Angle |
|---|---|---|
| Povilas Korop | AI Coding Daily | Coding workflows |
| Theo | YouTube, t3.gg | His own codebases, cost |
| Sam Witteveen | YouTube | Builders, open and local models |
| Every | Vibe Check | Business use |
| Zvi Mowshowitz | Don't Worry About the Vase | System cards, reactions |
| Ethan Mollick | One Useful Thing | Education and work |
Other modalities
General or specialised
What goes in, what comes out
Voice: three models or one
Text to image
Text to video with audio
Text to speech
Speech to text
Music with vocals
The main line and the side paths
Next: agents
Orchestration is moving into training
Thank you
Thank you
Dominik Lukes · AI Competency Centre, University of Oxford